Studying repeat blood donation from donation history
Blood services can study donation history to plan outreach. This research example classifies whether a donor gave blood in the dataset's recorded outcome period, using recency, frequency and time since the first donation.
1. Clinical question and intended use
Blood services can study donation history when planning outreach. The endpoint here is a recorded return to donate in a particular month, so the model concerns participation rather than donor eligibility.
Donation history
Use the three history variables retained by the final network.
Return behaviour
Compare model scores with donation in March 2007.
Outreach research
Evaluate contact policies separately from medical eligibility screening.
2. Cohort, measurements and endpoint
The UCI Blood Transfusion Service Center dataset describes 748 donors from Hsin-Chu City, Taiwan. Its endpoint is donation in March 2007. The supplied model uses three history variables; it does not assess medical eligibility to donate.
The downloadable project, saved report and supplied source CSV define the exact version used here. Repository: original dataset/source record.
| Subset | Records |
|---|---|
| Training | 450 |
| Validation / selection | 149 |
| Testing | 149 |
| Unused | 0 |
| Variable | Role | Type | Encoding | Unit |
|---|---|---|---|---|
| recency | Input | Numeric | months | |
| frequency | Input | Numeric | donations | |
| time | Input | Numeric | months | |
| donation | Target | Binary | no; yes | As supplied |
Interactive chart: donation pie chart. Enable JavaScript to explore it.
Interactive chart: donation Pearson correlations chart. Enable JavaScript to explore it.
3. Model
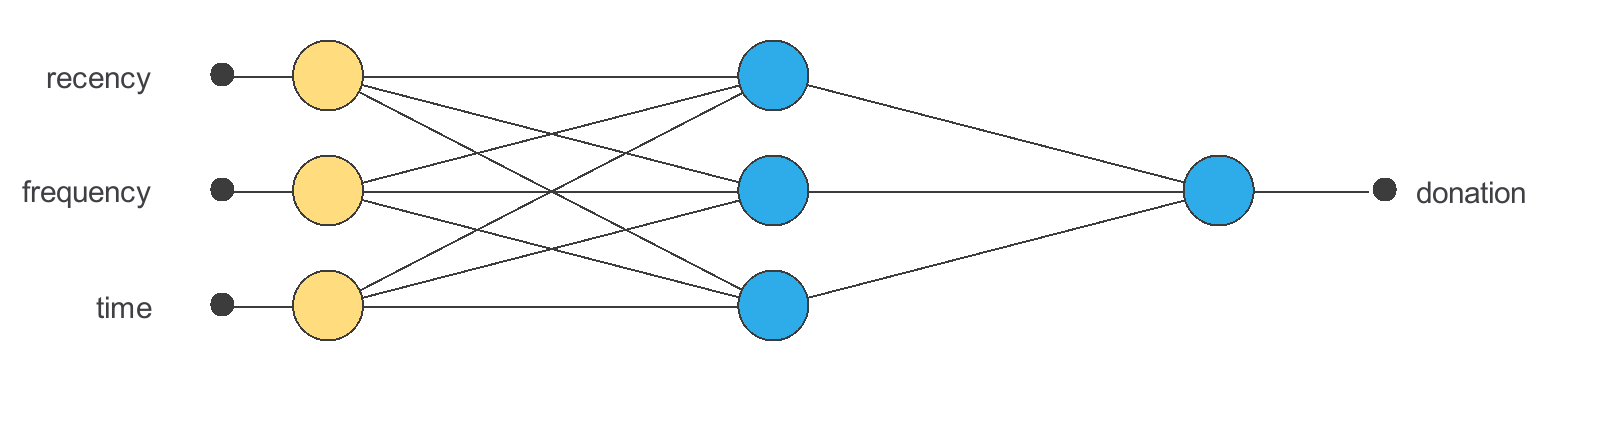
The final model has 3 encoded input features and 1 outputs. The following dimensions describe the final saved network.
| Layer | Input shape | Output shape | Activation |
|---|---|---|---|
| Scaling | 3 | 3 | — |
| Dense | 3 | 3 | Tanh |
| Dense | 3 | 1 | Sigmoid |
Output semantics: the sigmoid score increases toward yes; no is the other class. Calibration has not been evaluated, so scores are not presented as calibrated probabilities.
4. Training strategy
The saved training configuration uses WeightedSquaredError with QuasiNewton. Training minimizes the recorded objective; the validation subset monitors generalization during fitting. The testing subset is used for the evaluation below.
Interactive chart: Quasi-Newton method error history. Enable JavaScript to explore it.
Quasi-Newton method results
| Measure | Value |
|---|---|
| Epochs number | 118 |
| Elapsed time | 00:00:00 |
| Stopping criterion | Maximum validation error increases |
| Training error | 0.638 |
| Validation error | 0.629 |
5. Model selection and baseline
No model selection experiment is recorded in this supplied project. The displayed architecture is the trained model used for testing; earlier article claims about a different selected architecture do not apply to this version.
A transparent test-set comparator is the majority-class rule, with accuracy 76.5%. This is a baseline for interpretation, not an alternative model fitted on the test labels.
6. Clinical validation
The final classifier is evaluated on 149 testing records. The confusion counts below were reproduced from the saved model. Rows are actual classes and columns are predicted classes. The decision threshold is 0.5 on the score for yes.
Test class prevalence is shown by the support counts. Accuracy is 71.8% and macro F1 is 0.677. ROC AUC is 0.774. The native ROC optimal threshold is descriptive of this test set and is not an independently validated operating policy.
| Actual / predicted | no | yes | Total |
|---|---|---|---|
| no | 80 | 34 | 114 |
| yes | 8 | 27 | 35 |
| Class | Test cases | Sensitivity / recall | Specificity | Precision / PPV | F1 |
|---|---|---|---|---|---|
| no | 114 | 70.2% | 77.1% | 90.9% | 0.792 |
| yes | 35 | 77.1% | 70.2% | 44.3% | 0.562 |
Interactive chart: ROC chart. Enable JavaScript to explore it.
7. Workflow and reproducibility
Validated inputs → saved preprocessing → neural network → score or estimate → domain review. The ZIP contains the original project, source CSV, schema, test metrics and standalone interactive chart exports. The project hash in the schema identifies this exact version.
Explore the exported model
This research demonstration runs locally in your browser. Values outside the training range are outside the validated domain and are rejected. A valid input range does not guarantee that a combination is physically or operationally plausible.
This is not a diagnosis and must not guide medical treatment or donor eligibility.
8. Safety, generalizability and governance
The cohort represents one historical service, not current donors across regions. Validate on later donor cohorts and assess outreach effects separately. Eligibility, consent and contact policies require expert review. There is no external validation or evidence of a clinical benefit from this score.
No external validation or independent calibration study is included. Preprocessing statistics and model choices should be refitted within a prospective or grouped validation design. Correlations and directional responses describe associations, not causes. Human review is required before an operational decision.
Confidence intervals, subgroup performance, calibration curves and decision-cost validation are not established by these tasks. Predictive values apply to the observed test class distribution and may change when prevalence shifts.