Models describe a real-world system or process using mathematical concepts.
They are used to make decisions or predictions in various fields and sectors, including energy, medicine, and marketing.
In this regard, machine learning is a part of artificial intelligence that deals with building models without requiring explicit programming.
In the machine learning field, a model is sometimes referred to as a hypothesis.
Supervised learning is the most common paradigm within machine learning.
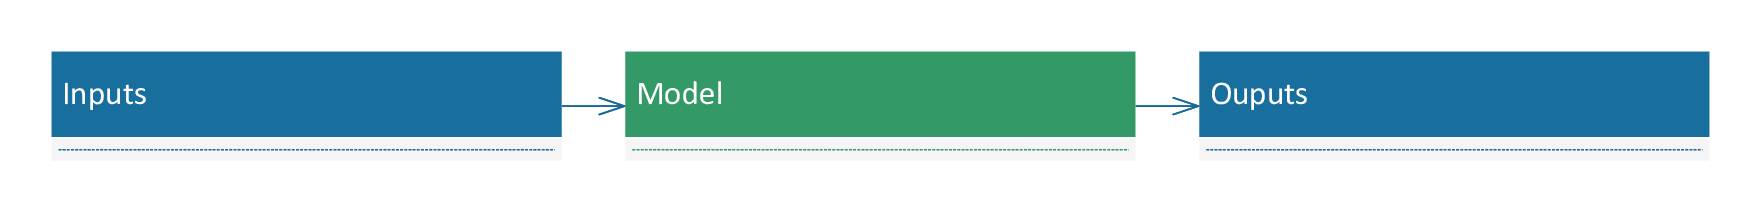
We can define it as the task of learning a function that maps an input to an output based on example input-output pairs.
A supervised learning algorithm analyzes the training data and produces an inferred function to map new examples.
In supervised learning, each example is a pair consisting of an input object and the desired output value.
An optimal scenario will enable the algorithm to determine the class labels for unseen instances accurately.
In this sense, generalization refers to a model’s ability to adapt correctly to new, previously unseen data from the same domain as the one used to create the model.
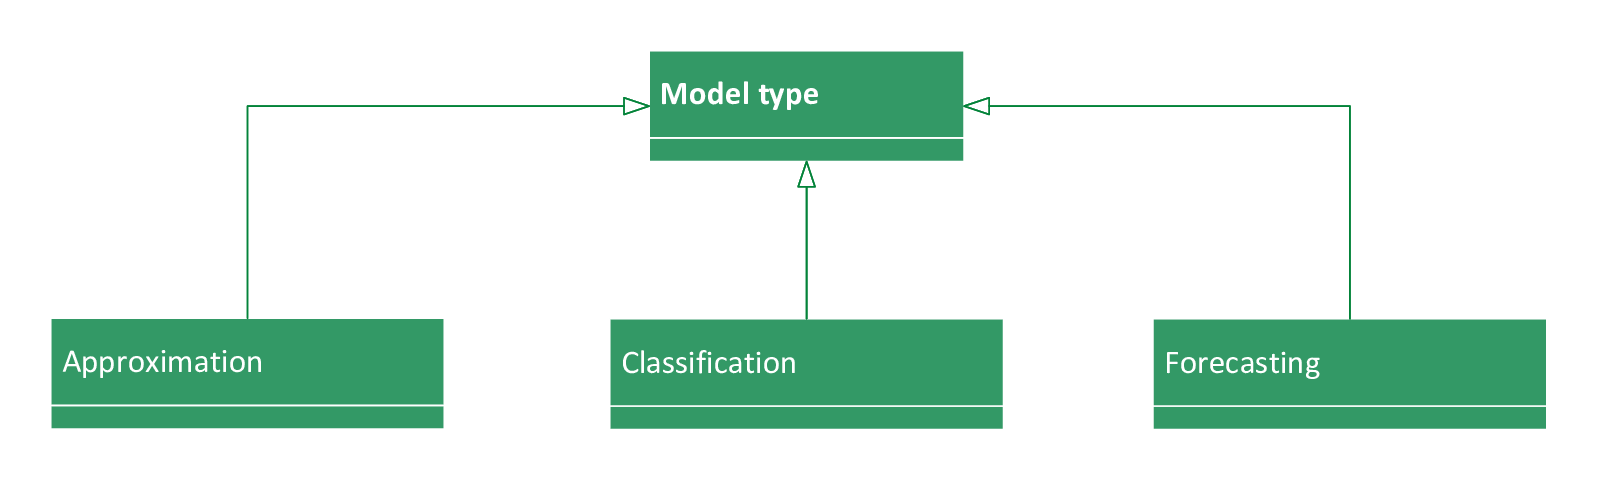
The most important types of models in machine learning are approximation, classification, and forecasting.
They allow us to discover relationships, recognize patterns, and predict trends from data, respectively.
Contents
1. Approximation
An approximation model estimates the value of one or more continuous variables from the values of a set of input variables.
To build it, we need a data set in which every sample contains the values of the inputs together with the observed values of the targets.
During training, the model adjusts its parameters until its outputs come as close as possible to those targets.
Once trained, the model can be evaluated for input values it has never seen, which is what makes it useful.
The following figure illustrates an approximation problem.
The objective here is to estimate the value of y, knowing the value of x. Figure \ ref{ApproximationFigure} illustrates a dataset with 21 samples, one input variable (x), and one target variable (y).
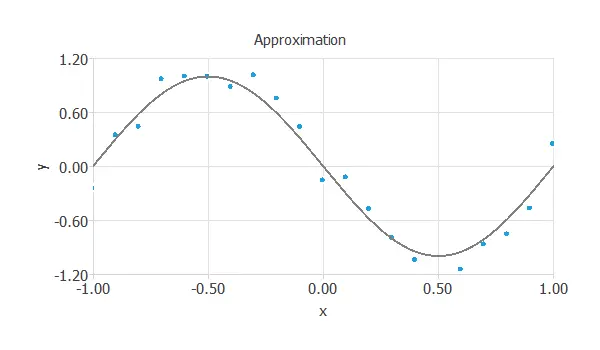
It also shows the corresponding approximation model.
The following is an example of an approximation model in the industrial sector.
Example: Reducing the gas emissions of a combined cycle power plant using machine learning
A combined cycle power plant that generates electricity wants to reduce its emissions of polluting gases, such as nitrogen oxides, which are harmful to health.
The combined cycle power plant consists of gas, steam, and steam generators with heat recovery. Gaseous combustion generates electricity by driving steam turbines.
The power plant is equipped with sensors that record all the data. From this, the company builds a model. The shape of this model is shown in the following figure:
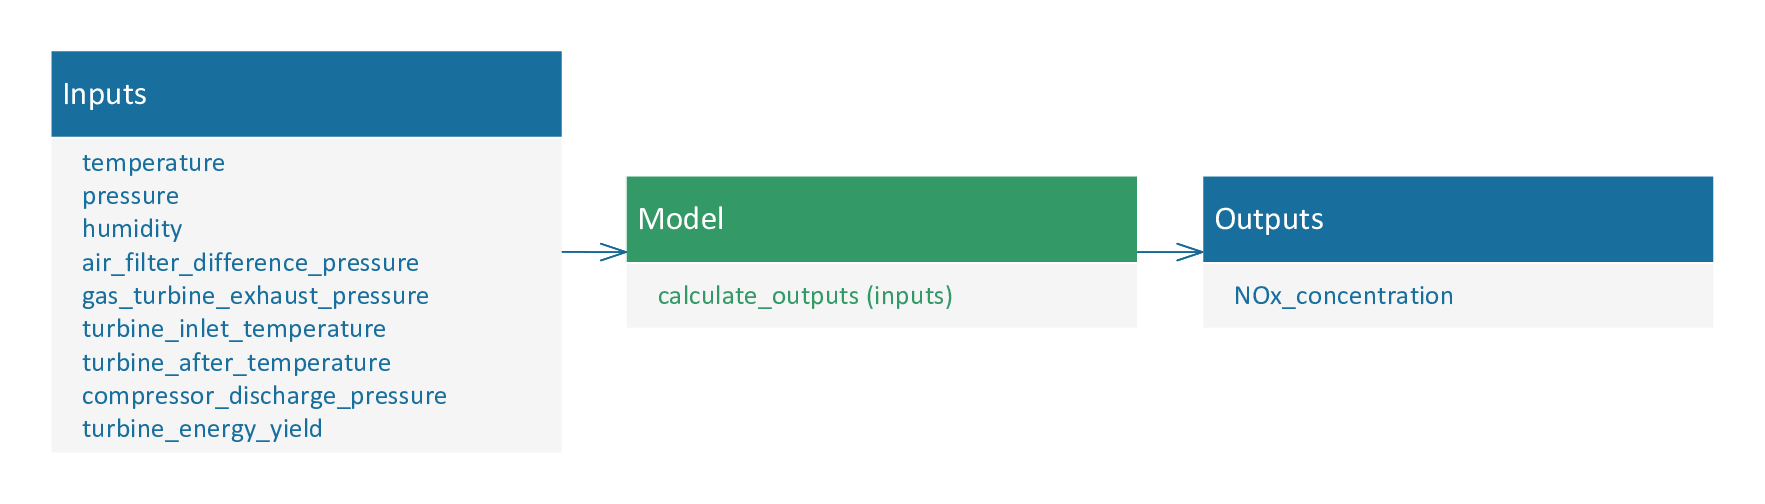
The input variables are atmospheric variables and plant-related variables. The model is created based on these data, and the values of nitrogen oxide emissions produced by the plant are estimated.
2. Classification
A classification model decides to which of a fixed set of categories each sample belongs.
When there are only two categories, such as true and false, we speak of binary classification.
For instance, a model can diagnose a breast tumor as malignant (true) or benign (false) from features measured on digitized images.
When the samples must be sorted into three or more categories, we speak of multiple classification.
The target variable is therefore categorical, and each category is encoded internally with binary values.
Medical diagnosis, customer churn prediction and quality inspection are typical applications.
A classification data set has the same layout as an approximation data set: one row per sample and one column per variable.
The difference lies in the target, which records the class of each sample instead of a measured quantity.
Rather than a bare label, the neural network returns, for each class, an estimate of the probability that the sample belongs to it given its inputs.
The predicted class is the most probable one or, in the binary case, the one selected by a decision threshold.
The following image shows a binary classification problem with two input variables:
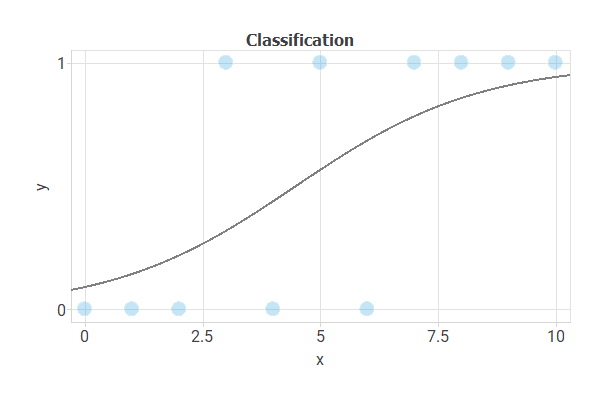
As with approximation, the goal is a neural network that generalizes well.
That is a model that can accurately classify new data.
The following is an example of an approximation model in the healthcare sector.
Example: Early detection of lung carcinoma
Lung cancer is the leading cause of cancer death worldwide. This type of cancer does not show up in testing until later, after which treatments become ineffective or have lower success rates. For this reason, lung cancer must be diagnosed as early as possible.
To enable the early detection of lung cancer, hospitals develop models that provide tools to support lung cancer risk assessment and management, facilitating discussions between individuals and their physicians about prevention and screening.
To build the model, a hospital creates a dataset containing lung cancer risk factors for 309 patients.
The form of this model is shown in the following figure:
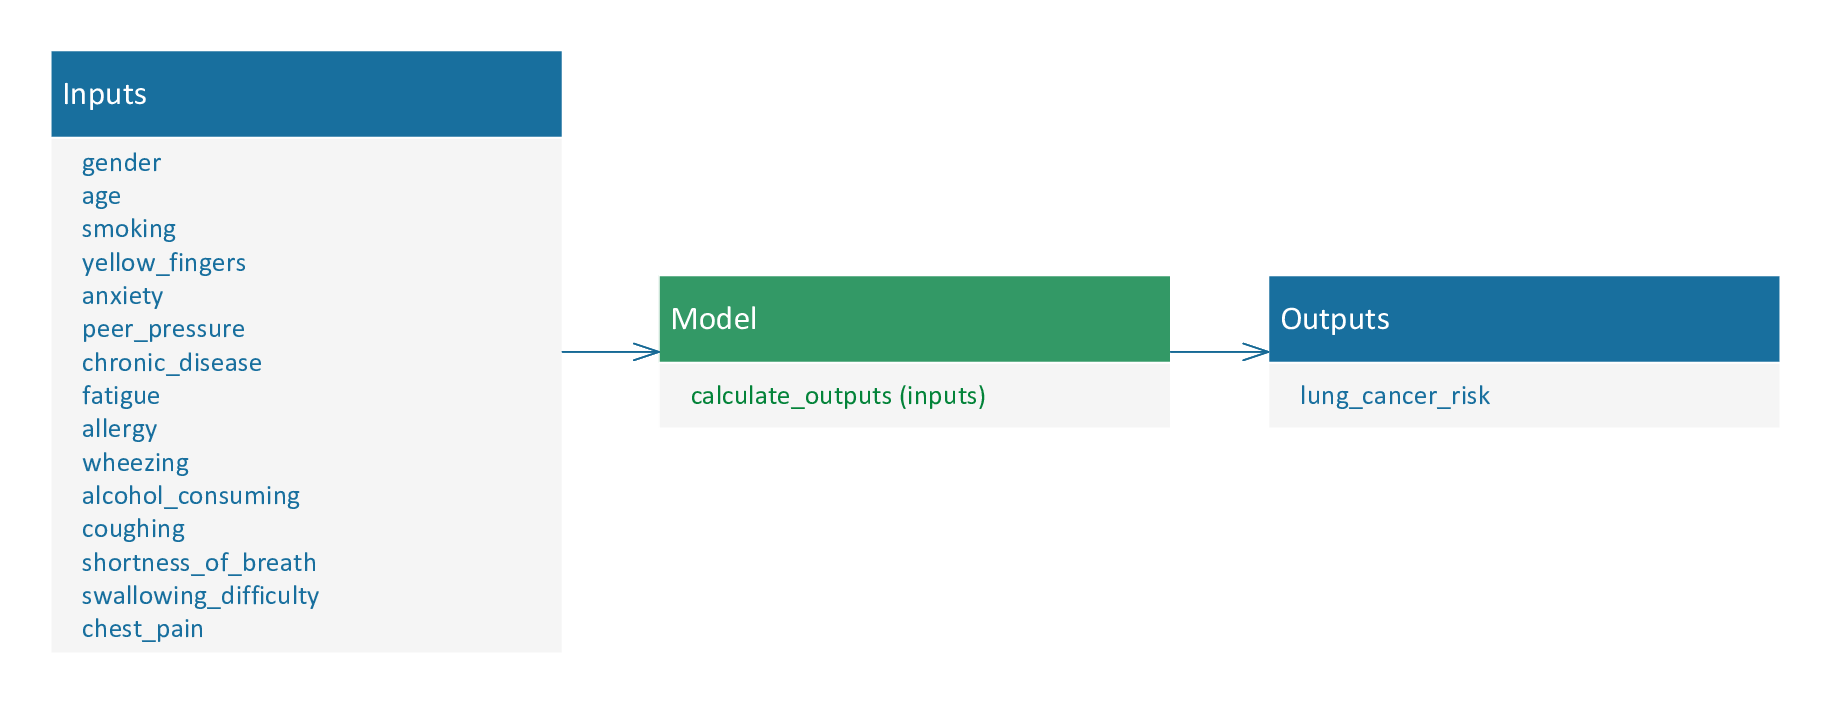
The model estimates the probability that a patient will develop lung cancer based on the clinical input variables.
This will allow the hospital to closely follow new patients with a high probability of developing lung cancer.
3. Forecasting
A forecasting model predicts future values of one or more variables from their past values and, optionally, from other variables recorded over time.
For example, a car manufacturer can forecast the sales of a model for the coming months from past sales, marketing actions and macroeconomic variables.
The following figure illustrates a forecasting model:
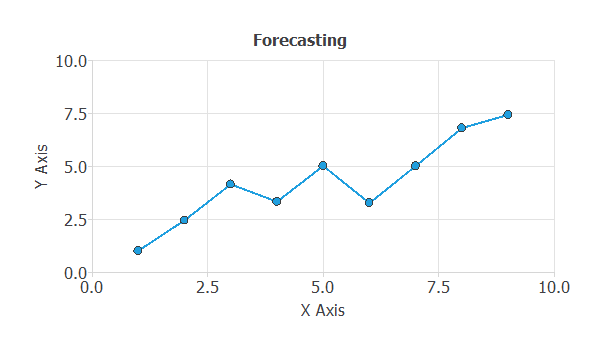
The data form a time series: each row holds the values of the variables at one instant, and the rows are ordered in time at a fixed interval, such as an hour, a day or a month.
To train a neural network, the series is rearranged into samples. The inputs of each sample are the most recent observations, called lags, and the targets are the values at the following time steps.
From then on, the problem is solved like an approximation problem, with one important difference: the model must be evaluated on periods that come after those used to train it, because only that shows whether it can anticipate the future.
We will now illustrate how prediction models work with an example.
Example: Country’s inflation
A country’s government wants to predict next month’s inflation.
For this purpose, it uses a time series with macroeconomic variables.
A government uses data for the previous three months to predict a country’s inflation for the next month.
From these data, the following approximation model is created.
The following figure shows the model’s form.
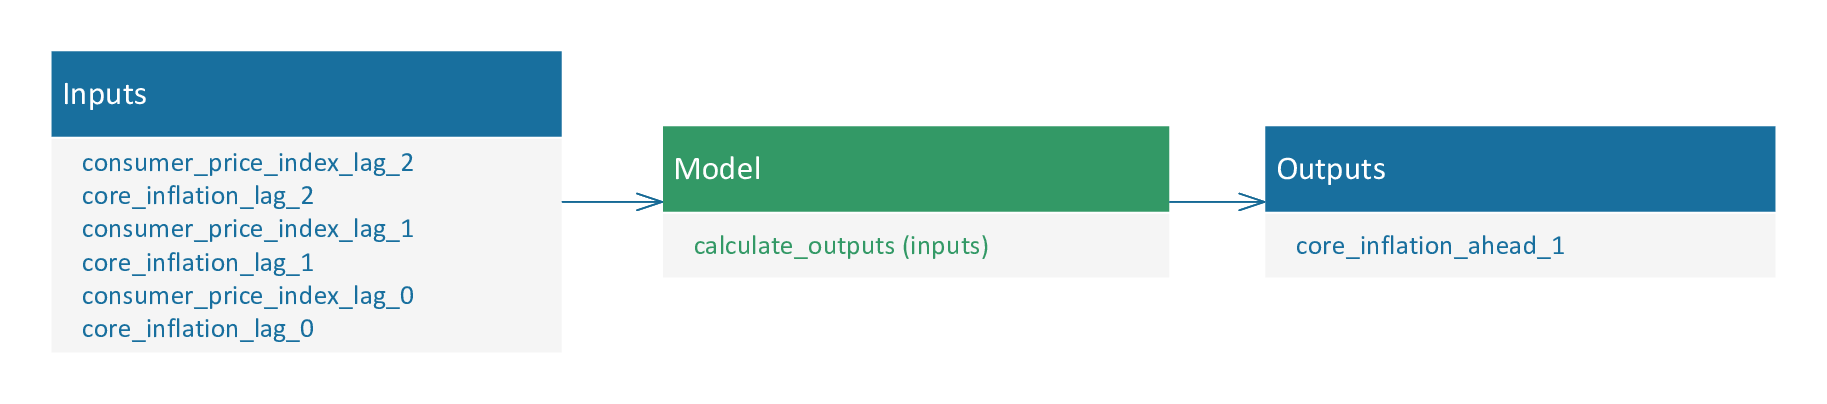
Based on the inflation and consumer price index of the previous three months, the model is created to predict next month’s inflation.
This forecasting will allow the government to take corresponding measures as inflation rises or falls.
Conclusions
The main machine learning models are approximation, classification, and prediction models.
A model uses mathematical concepts to describe a real-world system or process.
Good generalizability is the central objective when designing a model.
Tutorial video
You can watch the video tutorial to help you complete this article.
Build this model yourself with Neural Designer
Neural Designer is a no-code machine learning platform by Artelnics. Download it and train a model like this one on your own data, without writing code.